The integration of artificial intelligence into the landscape of public opinion polling has ushered in a transformative era for social science research, fundamentally altering how data is collected, processed, and analyzed. At the center of this shift is the deployment of large language models (LLMs) tasked with simulating diverse human personas to predict societal trends and political leanings. This methodological evolution, while offering unprecedented speed and scalability, has introduced complex questions regarding the authenticity of digital respondents and the fidelity of simulations when compared to traditional, human-led survey mechanisms. As polling organizations increasingly turn to synthetic data to augment or replace expensive human focus groups, the necessity for robust frameworks to manage cognitive bias and role-consistency has never been more critical.
The Mechanization of Public Opinion
Historically, the efficacy of a public opinion survey relied on the random sampling of the population, ensuring that every demographic had an equal opportunity to contribute to the data set. The advent of AI-driven survey respondents, or "synthetic agents," seeks to replicate this process by assigning specific profiles—defined by socioeconomic, cultural, and geographic markers—to an algorithm. These models are instructed to navigate survey interfaces as a human would, complete with the limitations inherent to human cognition, such as incomplete information, emotional variability, and susceptibility to phrasing effects.
The primary objective of these simulations is to bridge the gap between the logistical limitations of traditional polling—which can take weeks and cost millions—and the real-time demands of political and corporate decision-makers. By roleplaying specific segments of the U.S. population, these AI entities allow researchers to test the potential impact of legislative proposals, marketing strategies, or social shifts in a controlled, virtual environment. However, this relies heavily on the quality of the initial profile data and the model’s ability to remain "in character" throughout a multi-question survey flow.
Chronology of AI Integration in Social Research
The transition toward AI-augmented surveying did not occur in a vacuum; it is the culmination of nearly a decade of advancements in natural language processing (NLP).
- 2015–2018: Early experiments in AI polling focused on sentiment analysis, where existing human survey data was fed into neural networks to predict future answers based on historical patterns.
- 2019–2021: The emergence of transformer-based models allowed for the first generation of generative agents. These agents could hold coherent conversations, though they struggled with long-term memory and maintaining a consistent persona over complex, multi-stage questionnaires.
- 2022–Present: With the release of advanced LLMs, researchers began assigning detailed, multi-faceted personas to agents. These agents are now capable of navigating web interfaces, interpreting visual cues, and adjusting their tone to reflect regional or educational backgrounds.
This timeline reflects a rapid shift from passive observation to active participation. The current state of the art involves "persona grounding," where the agent is continuously reminded of its demographic profile and past responses to ensure the simulated data remains statistically coherent.
Statistical Foundations and Supporting Data
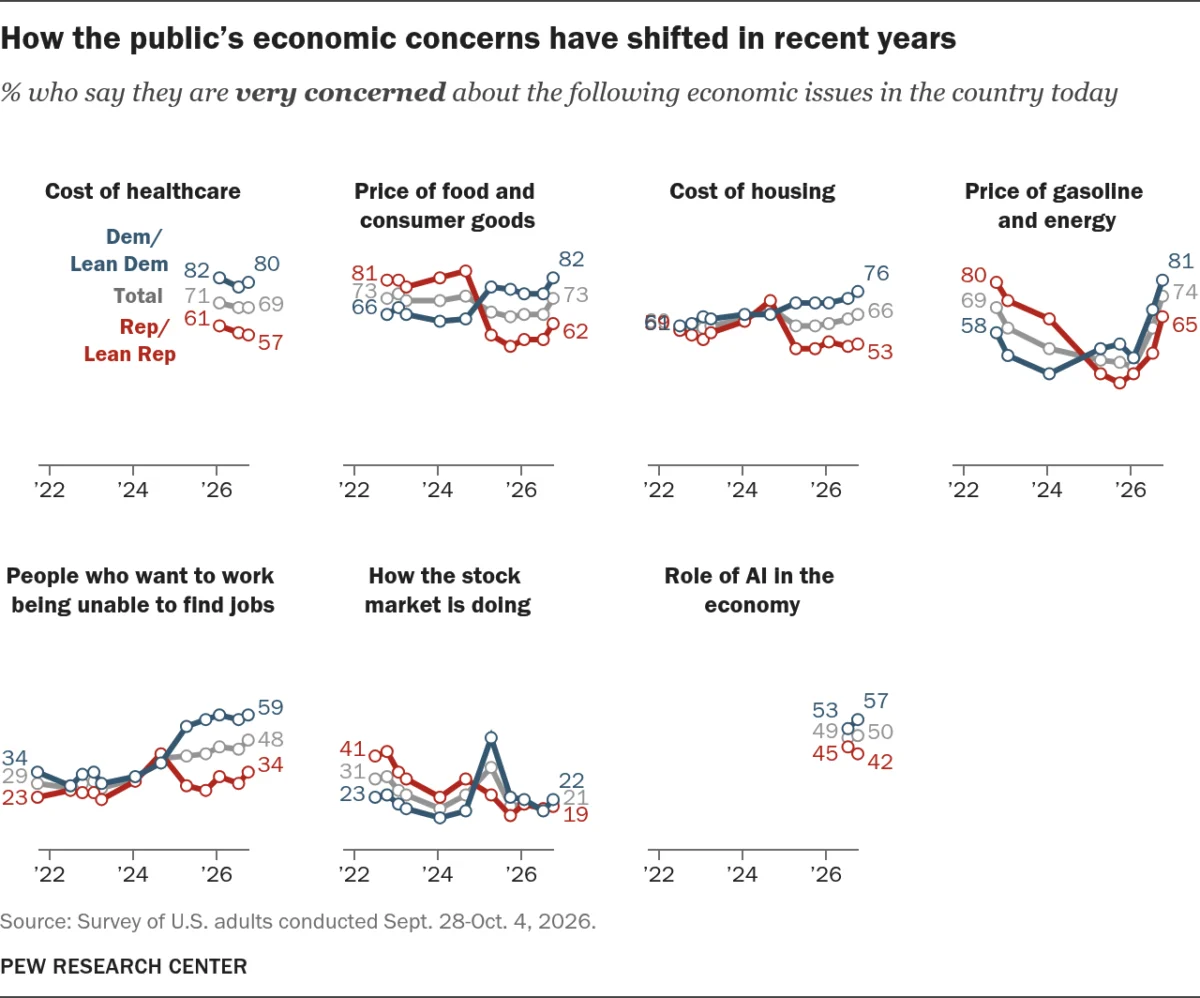
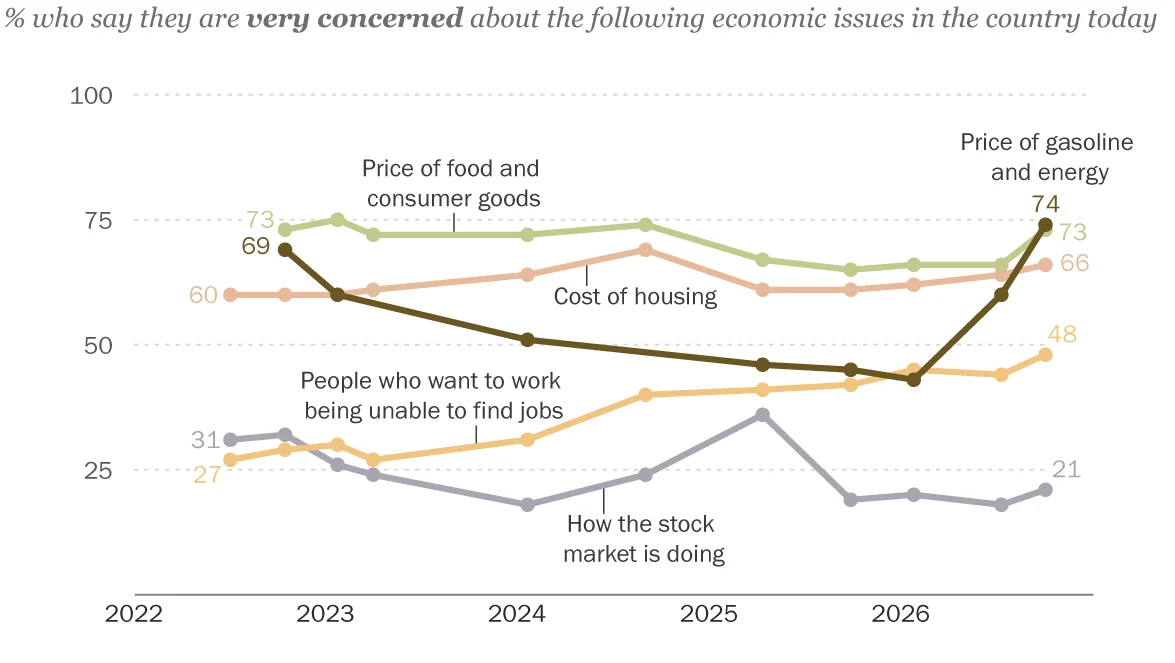
The validity of synthetic polling rests on the statistical alignment between synthetic results and verified human outcomes. Recent meta-analyses comparing AI-simulated respondents to traditional benchmarks have shown a high degree of correlation in closed-ended questions, particularly those concerning demographic-based economic preferences.
According to recent pilot studies, synthetic models correctly predict partisan voting behavior with an accuracy rate of approximately 82% when the training data is sufficiently granular. However, these models show a higher variance in open-ended responses, where the lack of genuine life experience can lead to "hallucinated" justifications or overly standardized language. Data indicates that while AI agents effectively simulate group-level trends, they often fail to replicate the "outlier" behavior observed in human populations—the unpredictable, irrational, or highly idiosyncratic responses that frequently define the results of real-world elections.
Official Perspectives and Ethical Considerations
The rise of AI in survey methodology has drawn mixed reactions from the research community. The American Association for Public Opinion Research (AAPOR) has recently emphasized the need for transparency in the use of synthetic data. The prevailing sentiment among industry experts is that while AI is an invaluable tool for "pre-testing" surveys, it should not be considered a wholesale replacement for human-representative sampling.
Dr. Elena Vance, a lead researcher in computational social science, notes: "The risk is not that the AI gives the wrong answer, but that it gives the ‘average’ answer too perfectly. Humans are messy, prone to error, and often inconsistent. If we build our policies based on a simulation that has been scrubbed of human fallibility, we may create systems that fail when they meet the complexities of the real world."
Conversely, proponents of the technology argue that synthetic polling allows for the inclusion of marginalized or hard-to-reach demographics that are traditionally underrepresented in standard telephone or web surveys. By adjusting the weight of synthetic profiles, researchers can create a more balanced representation of the national discourse, provided that the underlying models are audited for inherent biases in their training data.
The Cognitive Bias Challenge
A critical component of this methodology is the deliberate introduction of cognitive biases to mimic human behavior. Survey designers have long understood that factors such as question order, the "priming" of specific keywords, and the structure of response sets can significantly influence the respondent’s answer. In the context of AI, these biases must be programmed to ensure the simulation is "realistic."
For instance, an AI agent assigned a persona with low political engagement might be programmed to exhibit "satisficing"—the tendency to provide the quickest or least taxing answer to a survey question. Similarly, agents may be programmed to display social desirability bias, where they provide the response they believe is most socially acceptable rather than their true, persona-based preference. Managing these variables is the current frontier of the field; if the AI is too smart, it becomes an unreliable representative of the average citizen; if it is too simplistic, it fails to capture the nuance of human opinion.
Broader Implications for Democracy and Market Research
The implications of this technology are far-reaching. In the political sphere, the ability to rapidly simulate public opinion allows campaigns to "A/B test" rhetoric and policy messaging at a granular level. If a campaign can simulate how a specific demographic in a swing state will react to a specific turn of phrase, the potential for targeted micro-messaging is exponentially increased.
In market research, companies are using these simulations to model consumer reaction to product launches. The ability to iterate a survey thousands of times in a matter of minutes provides a level of predictive power that was previously impossible. Yet, this efficiency carries the risk of a feedback loop: if organizations use the same synthetic models to inform their strategies, they may inadvertently narrow the scope of public discourse, creating a "simulation echo chamber" where the data only reflects the biases of the underlying model.
As we move forward, the integration of AI in survey methodology will likely continue to accelerate. The focus must remain on the development of rigorous validation standards. Future research must prioritize the "human-in-the-loop" approach, ensuring that synthetic data is constantly calibrated against real-world human behavior. Only through this careful balance of computational power and human oversight can researchers ensure that the tools of the future do not distort the very opinions they seek to measure. The challenge is to maintain the integrity of the survey as a mirror to society, rather than allowing it to become a lens that only reflects the design choices of the programmer.