The promise of synthetic survey research—the use of Large Language Models (LLMs) to simulate human public opinion—has been met with significant skepticism following the latest findings from the Pew Research Center. As AI developers push toward more sophisticated reasoning capabilities, the potential for these "digital twins" to replicate the nuanced, often contradictory, and deeply personal views of the American electorate has become a focal point of computational social science. However, new experimental data suggests that while AI models can achieve varying degrees of accuracy on specific topics, they remain fundamentally unable to serve as a universal substitute for traditional, human-led survey methodology.
The study, which evaluated the performance of advanced models like OpenAI’s GPT-5.1 and Anthropic’s Claude Opus 4.6 against established American Trends Panel (ATP) data, reveals a fractured landscape where no single model possesses a comprehensive grasp of the American public consciousness. Instead, the research highlights a "specialization" effect: different models excel at capturing distinct facets of social and political sentiment, yet they fall short of providing a unified, reliable proxy for the broader population.
The Methodology of Synthetic Opinion
The experimentation process, conducted between January and April 2026, sought to determine if AI "digital twins"—models fed with extended profile information and instructed via expert reflection—could mirror the results of a high-quality, representative survey of U.S. adults. The researchers utilized a baseline survey conducted from January 20 to 26, 2026. This baseline served as the ground truth against which the AI simulations were measured.
The replication phase involved two distinct waves of testing. OpenAI’s GPT-5.1 was put to the test on March 2 and 3, followed by two separate iterations of Claude Opus 4.6, conducted on March 9-12 and April 7-10. By setting the models to "low reasoning" modes and providing them with demographic profiles, researchers attempted to minimize the models’ tendency toward neutral, middle-of-the-road responses, forcing them instead to adopt the specific socio-political outlooks of the simulated individuals.
Divergent Performance Metrics
The results of these simulations indicate that AI accuracy is highly topic-dependent. When researchers analyzed questions where each synthetic sample achieved an average absolute error of 5.0 percentage points or less compared to real human data, they found a stark divergence in model competence.
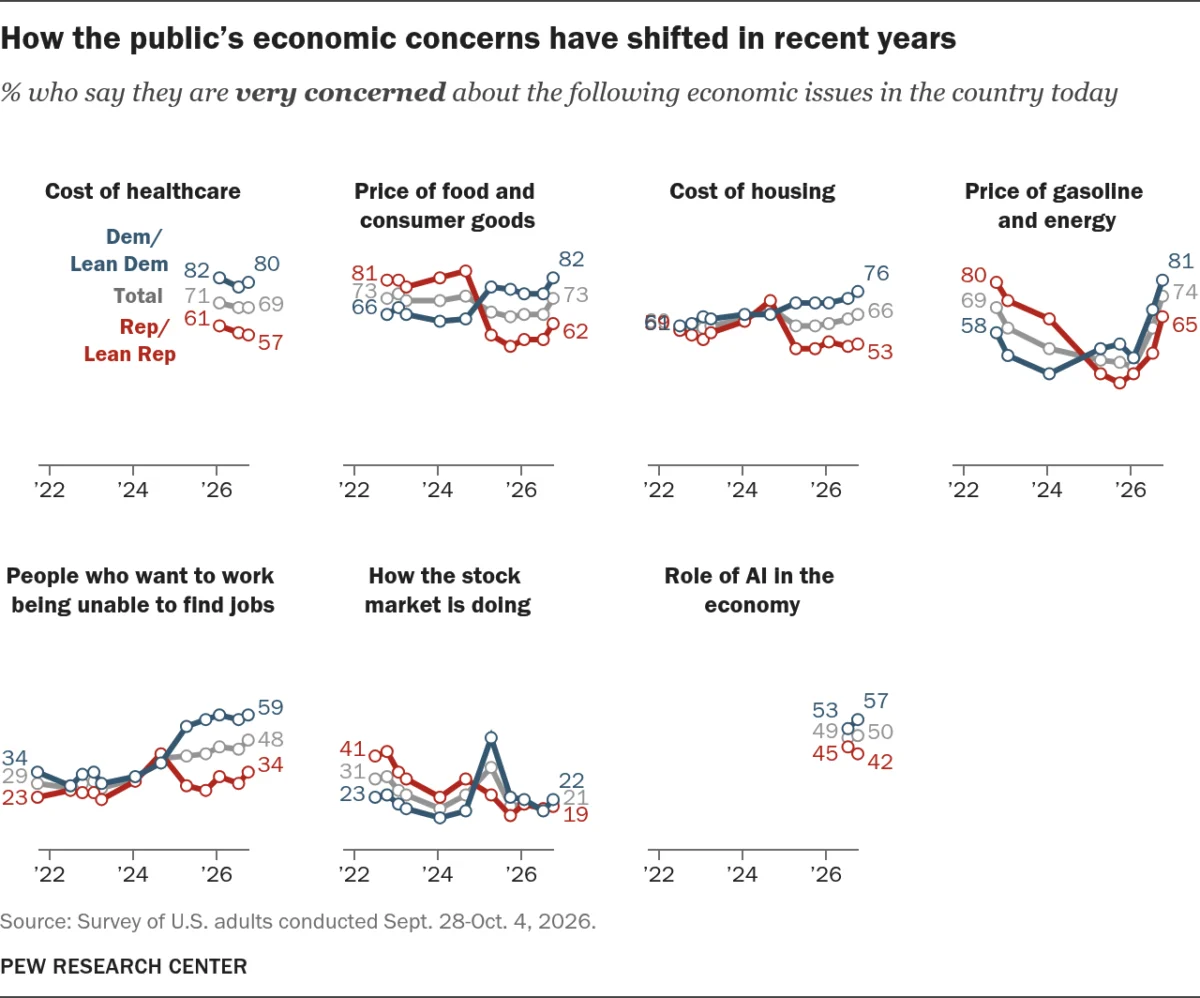
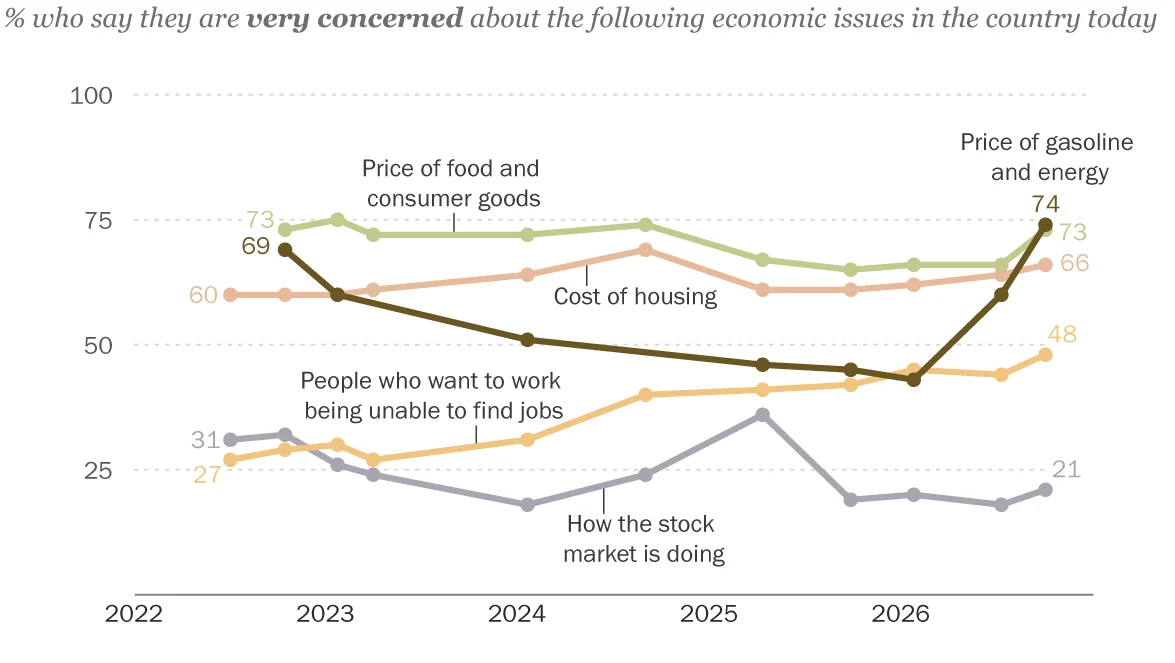
GPT-5.1 demonstrated a relative strength in addressing structural and demographic-adjacent questions. Its successful simulations included inquiries into the cost of housing, participation in political protests or campaigns, and perceptions regarding the 2026 outlook compared to 2025. Furthermore, the model showed a capacity to simulate views on specific administrative policies, such as the acceptability of federal immigration officers wearing face coverings and general approval ratings for the Trump presidency.
Conversely, Claude Opus 4.6 appeared more adept at navigating ideological and institutional sentiment. Its successful simulations covered complex areas such as satisfaction with the state of the country, the perceived influence of voting, and the nuanced dynamics of partisan cooperation in Congress. Additionally, Claude Opus 4.6 successfully mirrored human sentiment regarding abortion access, tariff policy effects, and personal interest in discussing politics with those holding opposing viewpoints.
Perhaps most revealing is the scarcity of overlap. The only topic where both models achieved high accuracy—maintaining an error rate of 5.0 percentage points or less—was the simple demographic and financial question: "Have an IRA, 401(k) or similar retirement account?" This suggests that while AI can accurately simulate basic socioeconomic indicators, its ability to capture ideological nuance remains inconsistent and model-specific.
The Limitations of Digital Twins
The failure of these models to provide a consistent, accurate output across all domains points to the "black box" nature of current AI architectures. Unlike human survey-takers, whose responses are informed by lived experience, cultural context, and biological reality, AI models operate on probabilistic patterns derived from vast, heterogeneous datasets. When an AI "answers" a survey, it is not expressing an opinion; it is predicting the most statistically likely response for a given profile based on its training data.
This distinction is critical for the future of political polling and market research. If an AI model is biased toward certain types of discourse or over-represents specific online viewpoints—which are often more polarized than the general population—it will inevitably produce skewed results. The fact that Claude Opus 4.6 and GPT-5.1 produced such different sets of "accurate" answers underscores that these models are not interchangeable, and that a researcher’s choice of model is, in itself, a variable that could bias the entire study.
Broader Implications for Social Science
The implications of this research are profound for the polling industry, which has faced a crisis of confidence in recent years due to declining response rates and the difficulty of reaching representative samples. The allure of synthetic surveys is clear: they are instantaneous, cost-effective, and capable of simulating millions of "participants" in seconds.
However, the Pew Research Center’s findings serve as a cautionary tale. If synthetic samples cannot reliably replicate real-world data, relying on them for policy-making or electoral forecasting could lead to significant miscalculations. Political campaigns and public policy institutions often use survey data to gauge the "pulse" of the electorate. If that pulse is being generated by a model’s internal biases rather than the actual thoughts of citizens, the resulting strategies could be disconnected from reality.
Furthermore, the ethical considerations are substantial. If synthetic populations are used to influence public opinion—by testing which messaging strategies "work" on simulated demographics—the potential for digital manipulation grows. This is especially relevant given the models’ varying performance on sensitive political topics like immigration, abortion, and executive leadership.
Expert Analysis and Future Outlook
Analysts in the field of computational social science suggest that the current iteration of AI is best suited for preliminary research, such as testing survey wording or developing hypotheses, rather than replacing traditional data collection. The "digital twin" approach requires highly specific, granular prompt engineering, which, as the study shows, is not yet a perfect science.
Looking ahead, the development of future models will likely focus on improving "reasoning" and context-awareness to close the gap between synthetic and real-world responses. However, the inherent variability observed in the 2026 study suggests that until there is a standardized, transparent method for tuning these models to human-like behavior, the "digital twin" remains a flawed mirror.
For now, the consensus among social researchers is that the human element remains indispensable. The nuances of human belief systems—shaped by localized events, personal history, and evolving social dynamics—are not yet captured in the weights and parameters of modern LLMs. Until AI can process the complexity of human life with greater consistency, the gold standard of public opinion research will remain the direct, human-to-human survey.
Chronology of the 2026 Experiments
- January 20–26, 2026: Pew Research Center conducts the primary survey of U.S. adults, serving as the benchmark for the study.
- March 2–3, 2026: Researchers initiate the first replication wave using OpenAI’s GPT-5.1.
- March 9–12, 2026: Researchers initiate the first replication wave using Anthropic’s Claude Opus 4.6.
- April 7–10, 2026: A secondary replication wave is conducted with Claude Opus 4.6 to verify findings and check for model stability.
- Post-April 2026: Data synthesis and comparative analysis performed to identify the "question-level average absolute error" and evaluate the efficacy of the synthetic samples.
As the industry moves forward, the focus will undoubtedly shift toward whether these models can eventually be "calibrated" to match human trends more reliably. Until then, the findings offer a sobering reminder that while AI is an incredibly powerful tool for data processing, it is not yet an instrument for capturing the authentic voice of the American public.